Introducing Audio Perception-1
Audio is one of the largest sources of unstructured data, and most of it is never listened to.
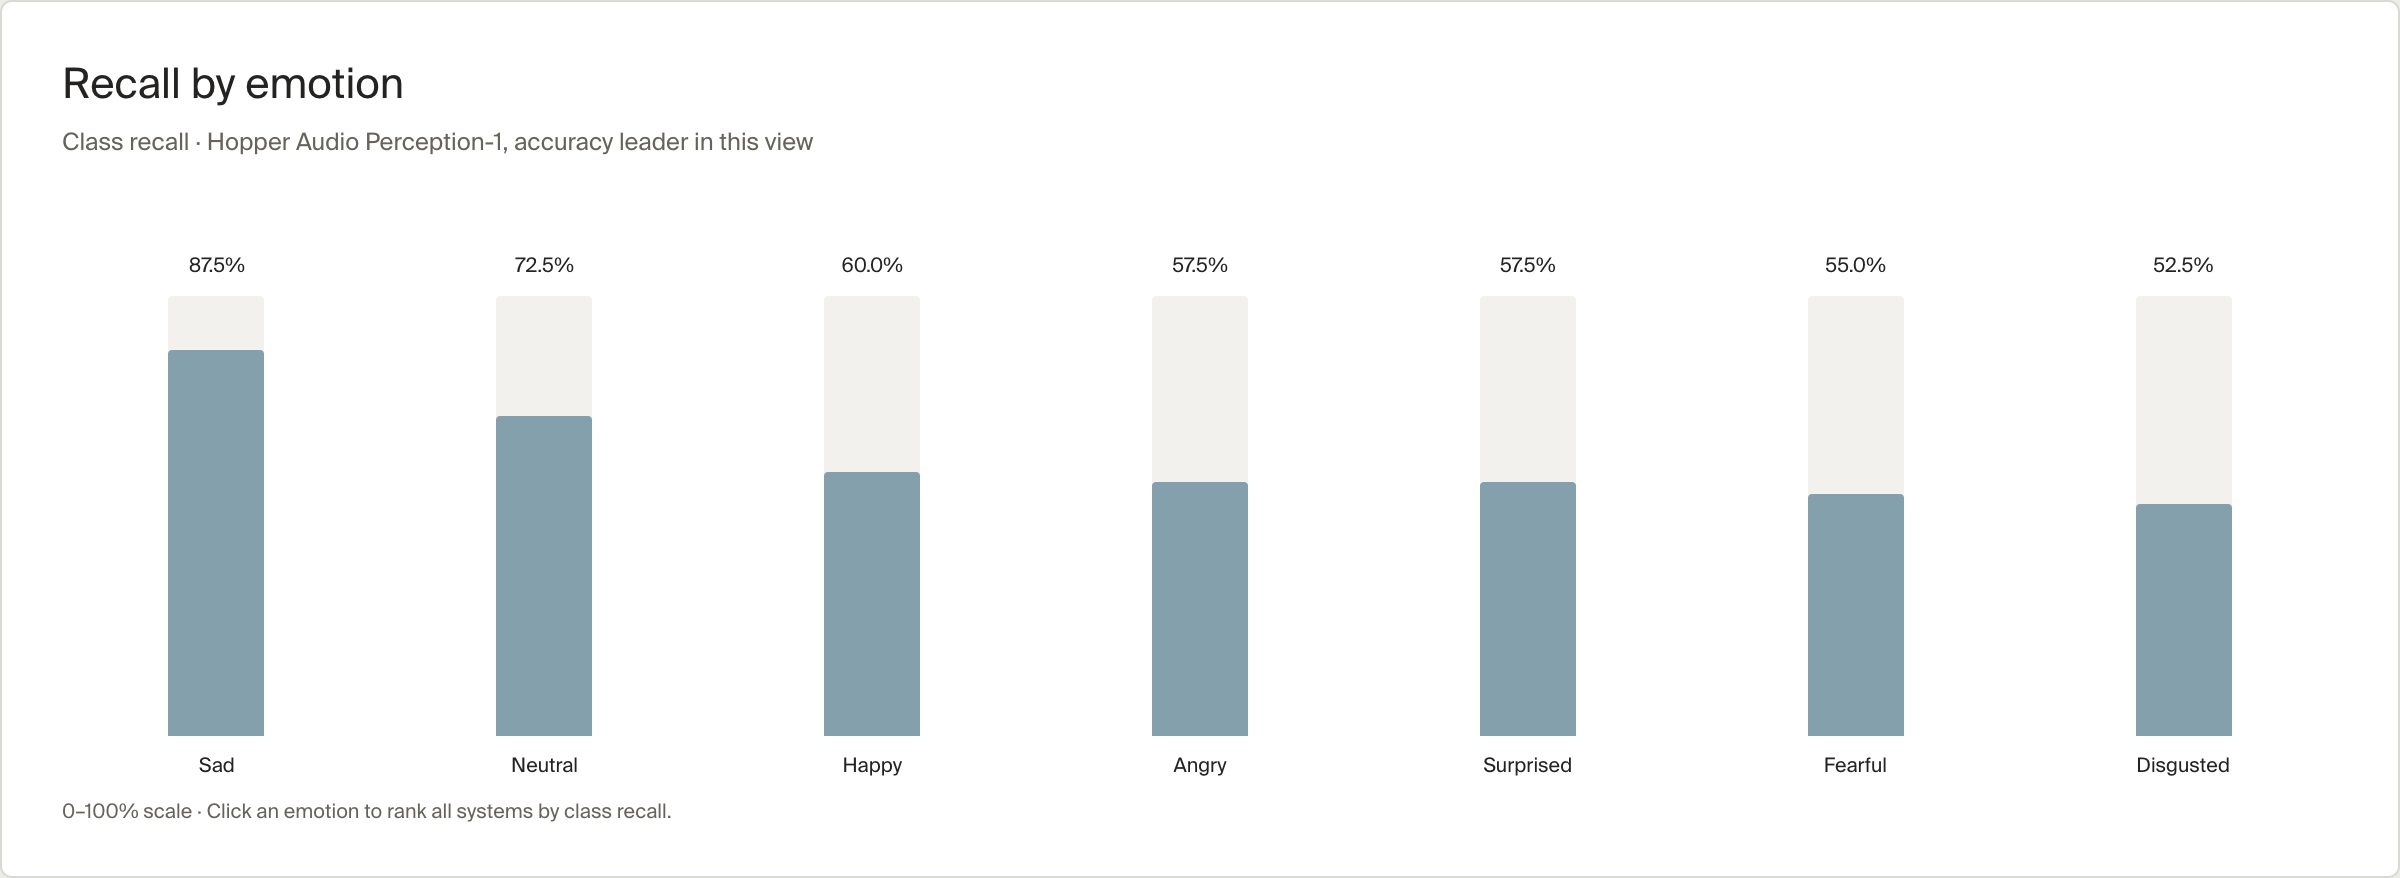
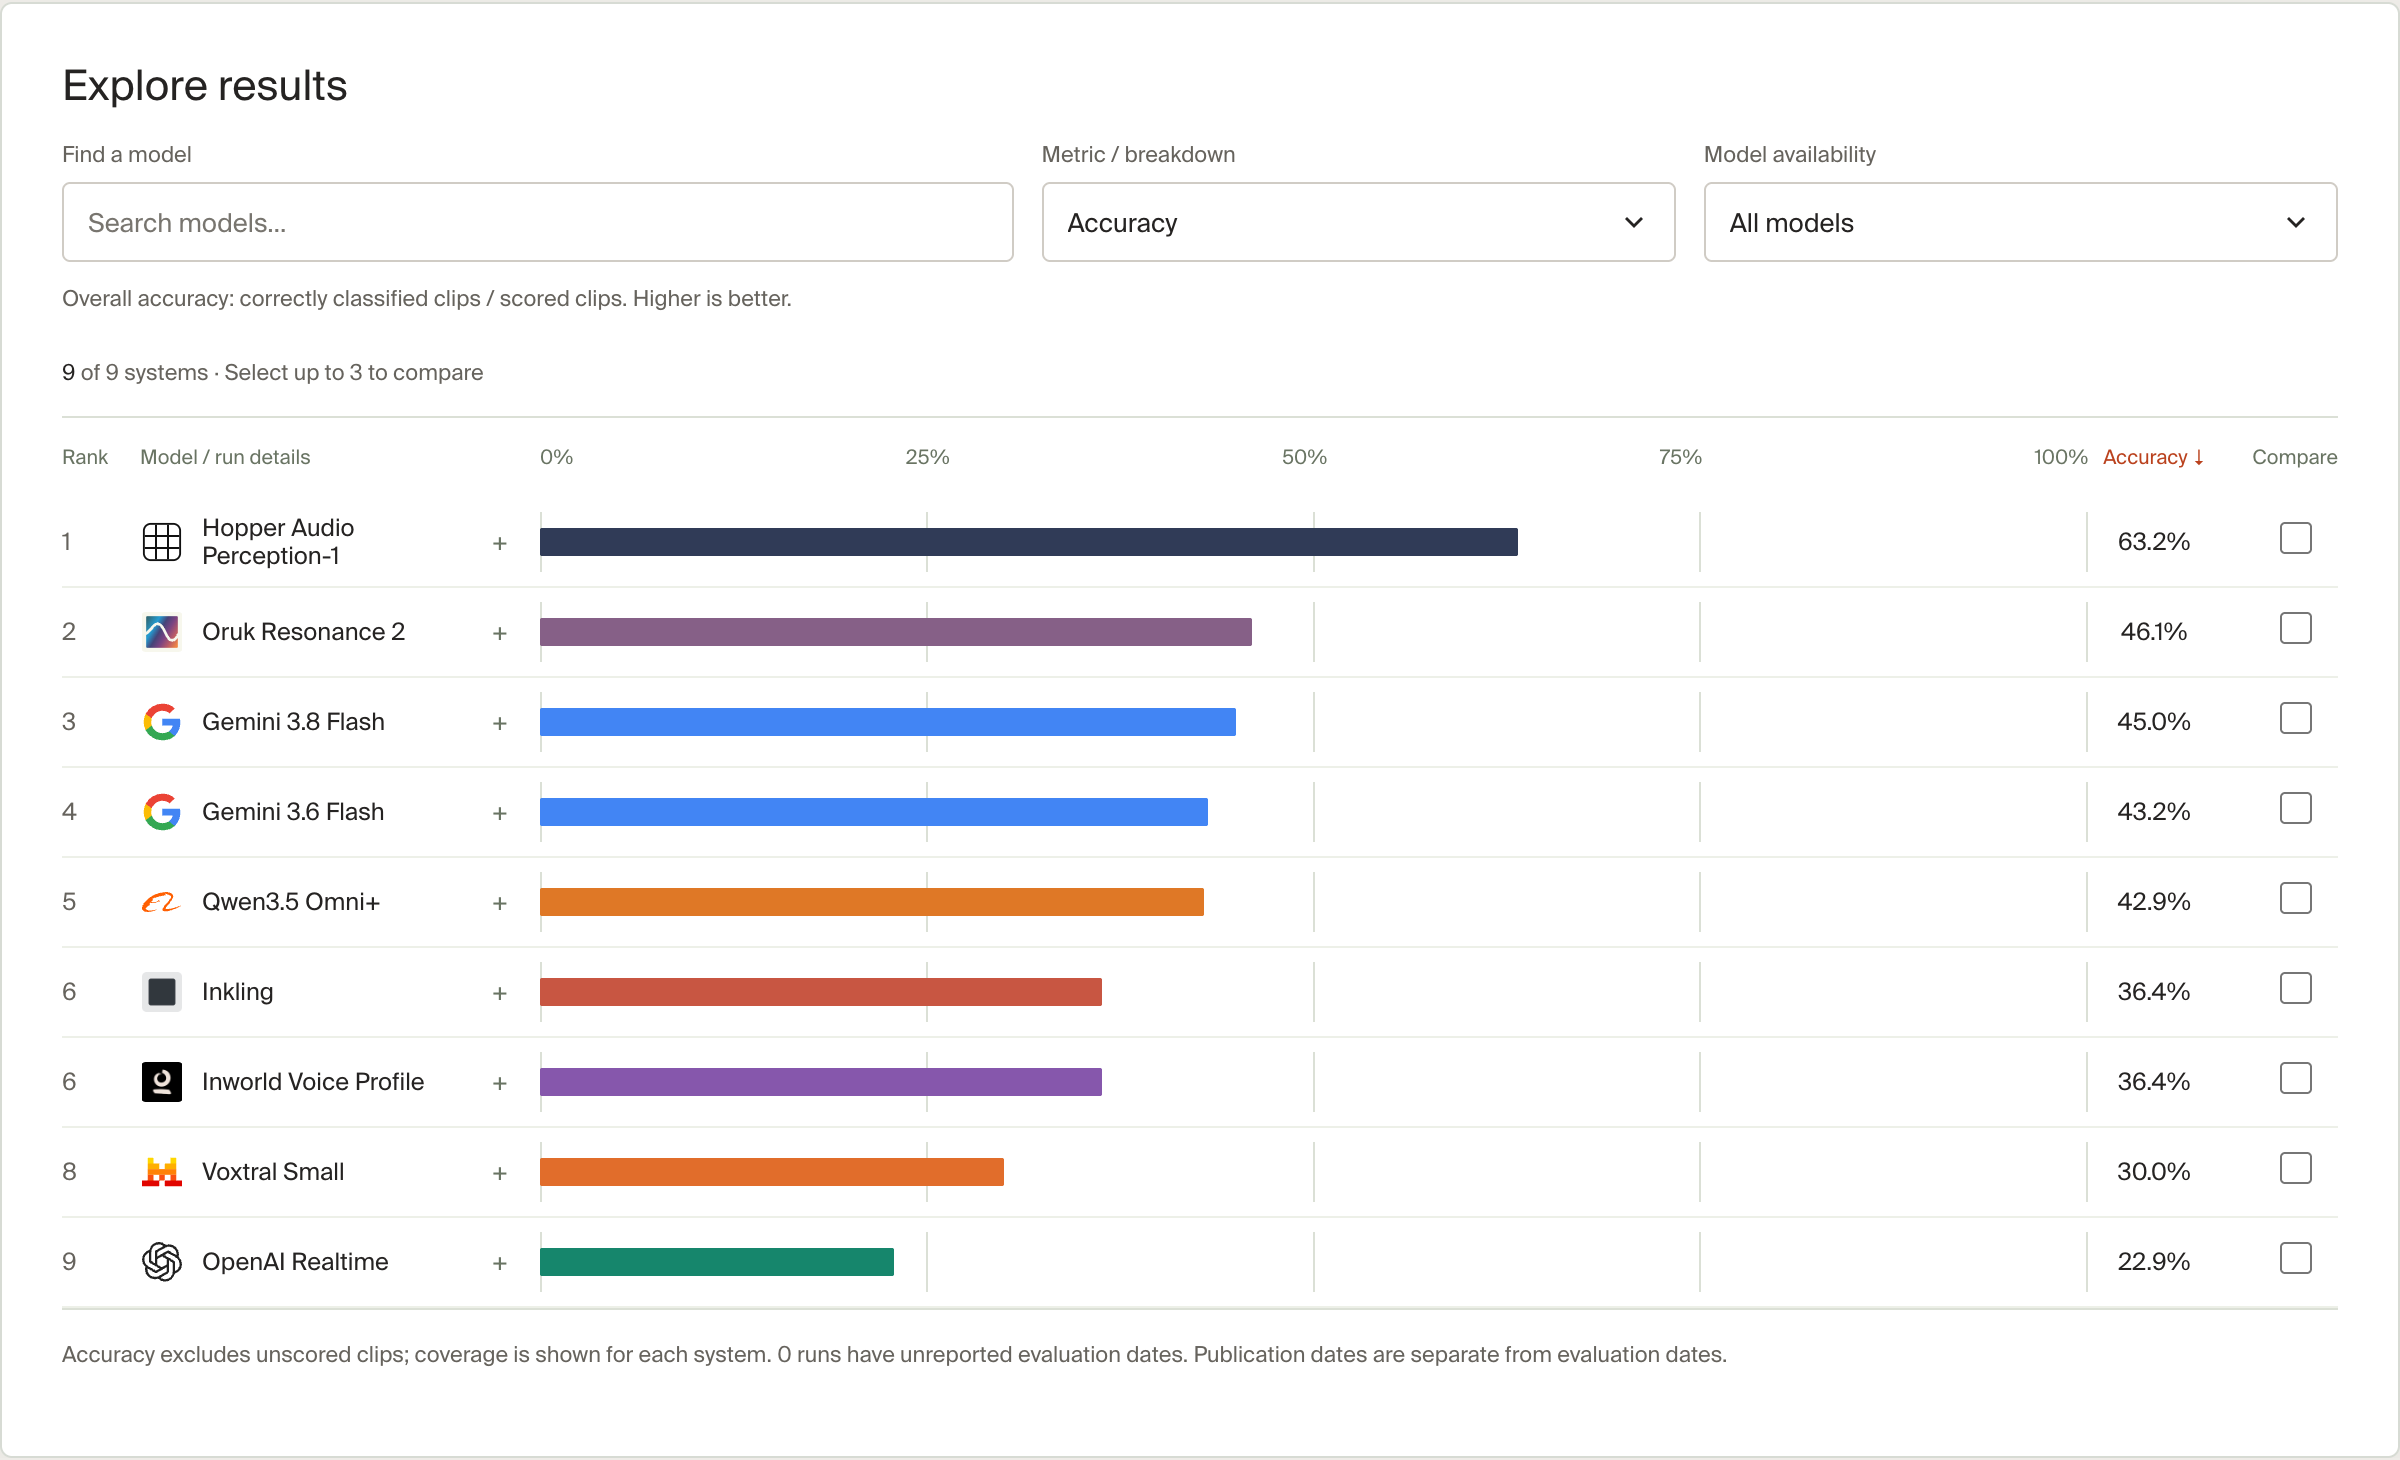
Today, we are excited to launch our first audio understanding model, Audio Perception-1, which is SOTA in emotion detection ahead of OpenAI and Gemini. It takes audio as input and outputs decisions.
Here are results on Besimple’s Vocal Affect Bench.
You can use it in the following ways:
If you're a robotics company
Give your robot ears (real ones):
- Hear a child crying.
- Understand pet sounds.
- Notice footsteps or glass breaking.
If you're a model training company
Use it as a verifier for RL:
- Score naturalness and emotion.
- Compare checkpoints without human raters.
If you're a voice agent company
Run it on your call recordings and ask:
- Did the customer get their task done? Yes/No
- Did the agent mispronounce any names?
- How would a human rate this call, 1–10?
Essentially, replace your manual QA of listening to calls.
How did we get here?
One of our customers is a gaming company that wanted us to post-train their TTS model. Their goal was to bring out accents and emotions better than ElevenLabs for NPCs.
We are a startup and didn't want to spend 6 figures on buying the training data. RL with verifiable rewards was our most promising path. Until now, most publicly available TTS research used RL mainly for things like word error rate and talking speed, which are easier to verify.
We looked at the existing LLMs that support audio input, but they are so bad and flaky that we decided to train our own model.